阿里 Qwen 发布 Qwen3.8-Flash-Next 开源权重模型
Qwen/Qwen3.8-Flash-Next
阿里 Qwen 团队发布 Qwen3.8-Flash-Next 开源权重模型,采用 Gated DeltaNet 与 Qwen Sparse Attention 混合注意力、Gated Residual 和 n-gram 嵌入,总参数 125B、激活 6B,另有 51B n-gram 嵌入参数。
原文给出新架构的组件设计与多基准对比,可据此判断稀疏注意力与 n-gram 嵌入在长上下文场景的取舍。
译文尚不完整,完整内容请切换到原文。
该仓库包含以 HF Mirror Transformers 格式提供的后训练模型的模型权重和配置文件。
这些产物兼容 HF Mirror Transformers、vLLM、SGLang、TokenSpeed 等。
对于希望获得托管式、可扩展推理且无需维护基础设施的用户,官方 Qwen API 服务由 Qwen Cloud 提供。
特别是,Qwen3.8-Flash 是基于 Qwen3.8-Flash-Next 的官方版本,具备更多生产特性,例如默认 1M 上下文长度、官方内置工具。更多信息请参阅 Qwen3.8-Flash 概览。
随着基础模型的前沿不断推向更大的参数量和更长的上下文窗口,问题不再仅仅是我们能扩展多少,而是我们能以多高的效率实现扩展。朝着惠及所有人的人工通用智能(AGI)的可持续进展需要架构创新。今天,我们分享这一方向上的一个具体进展:Qwen3.8-Flash-Next。
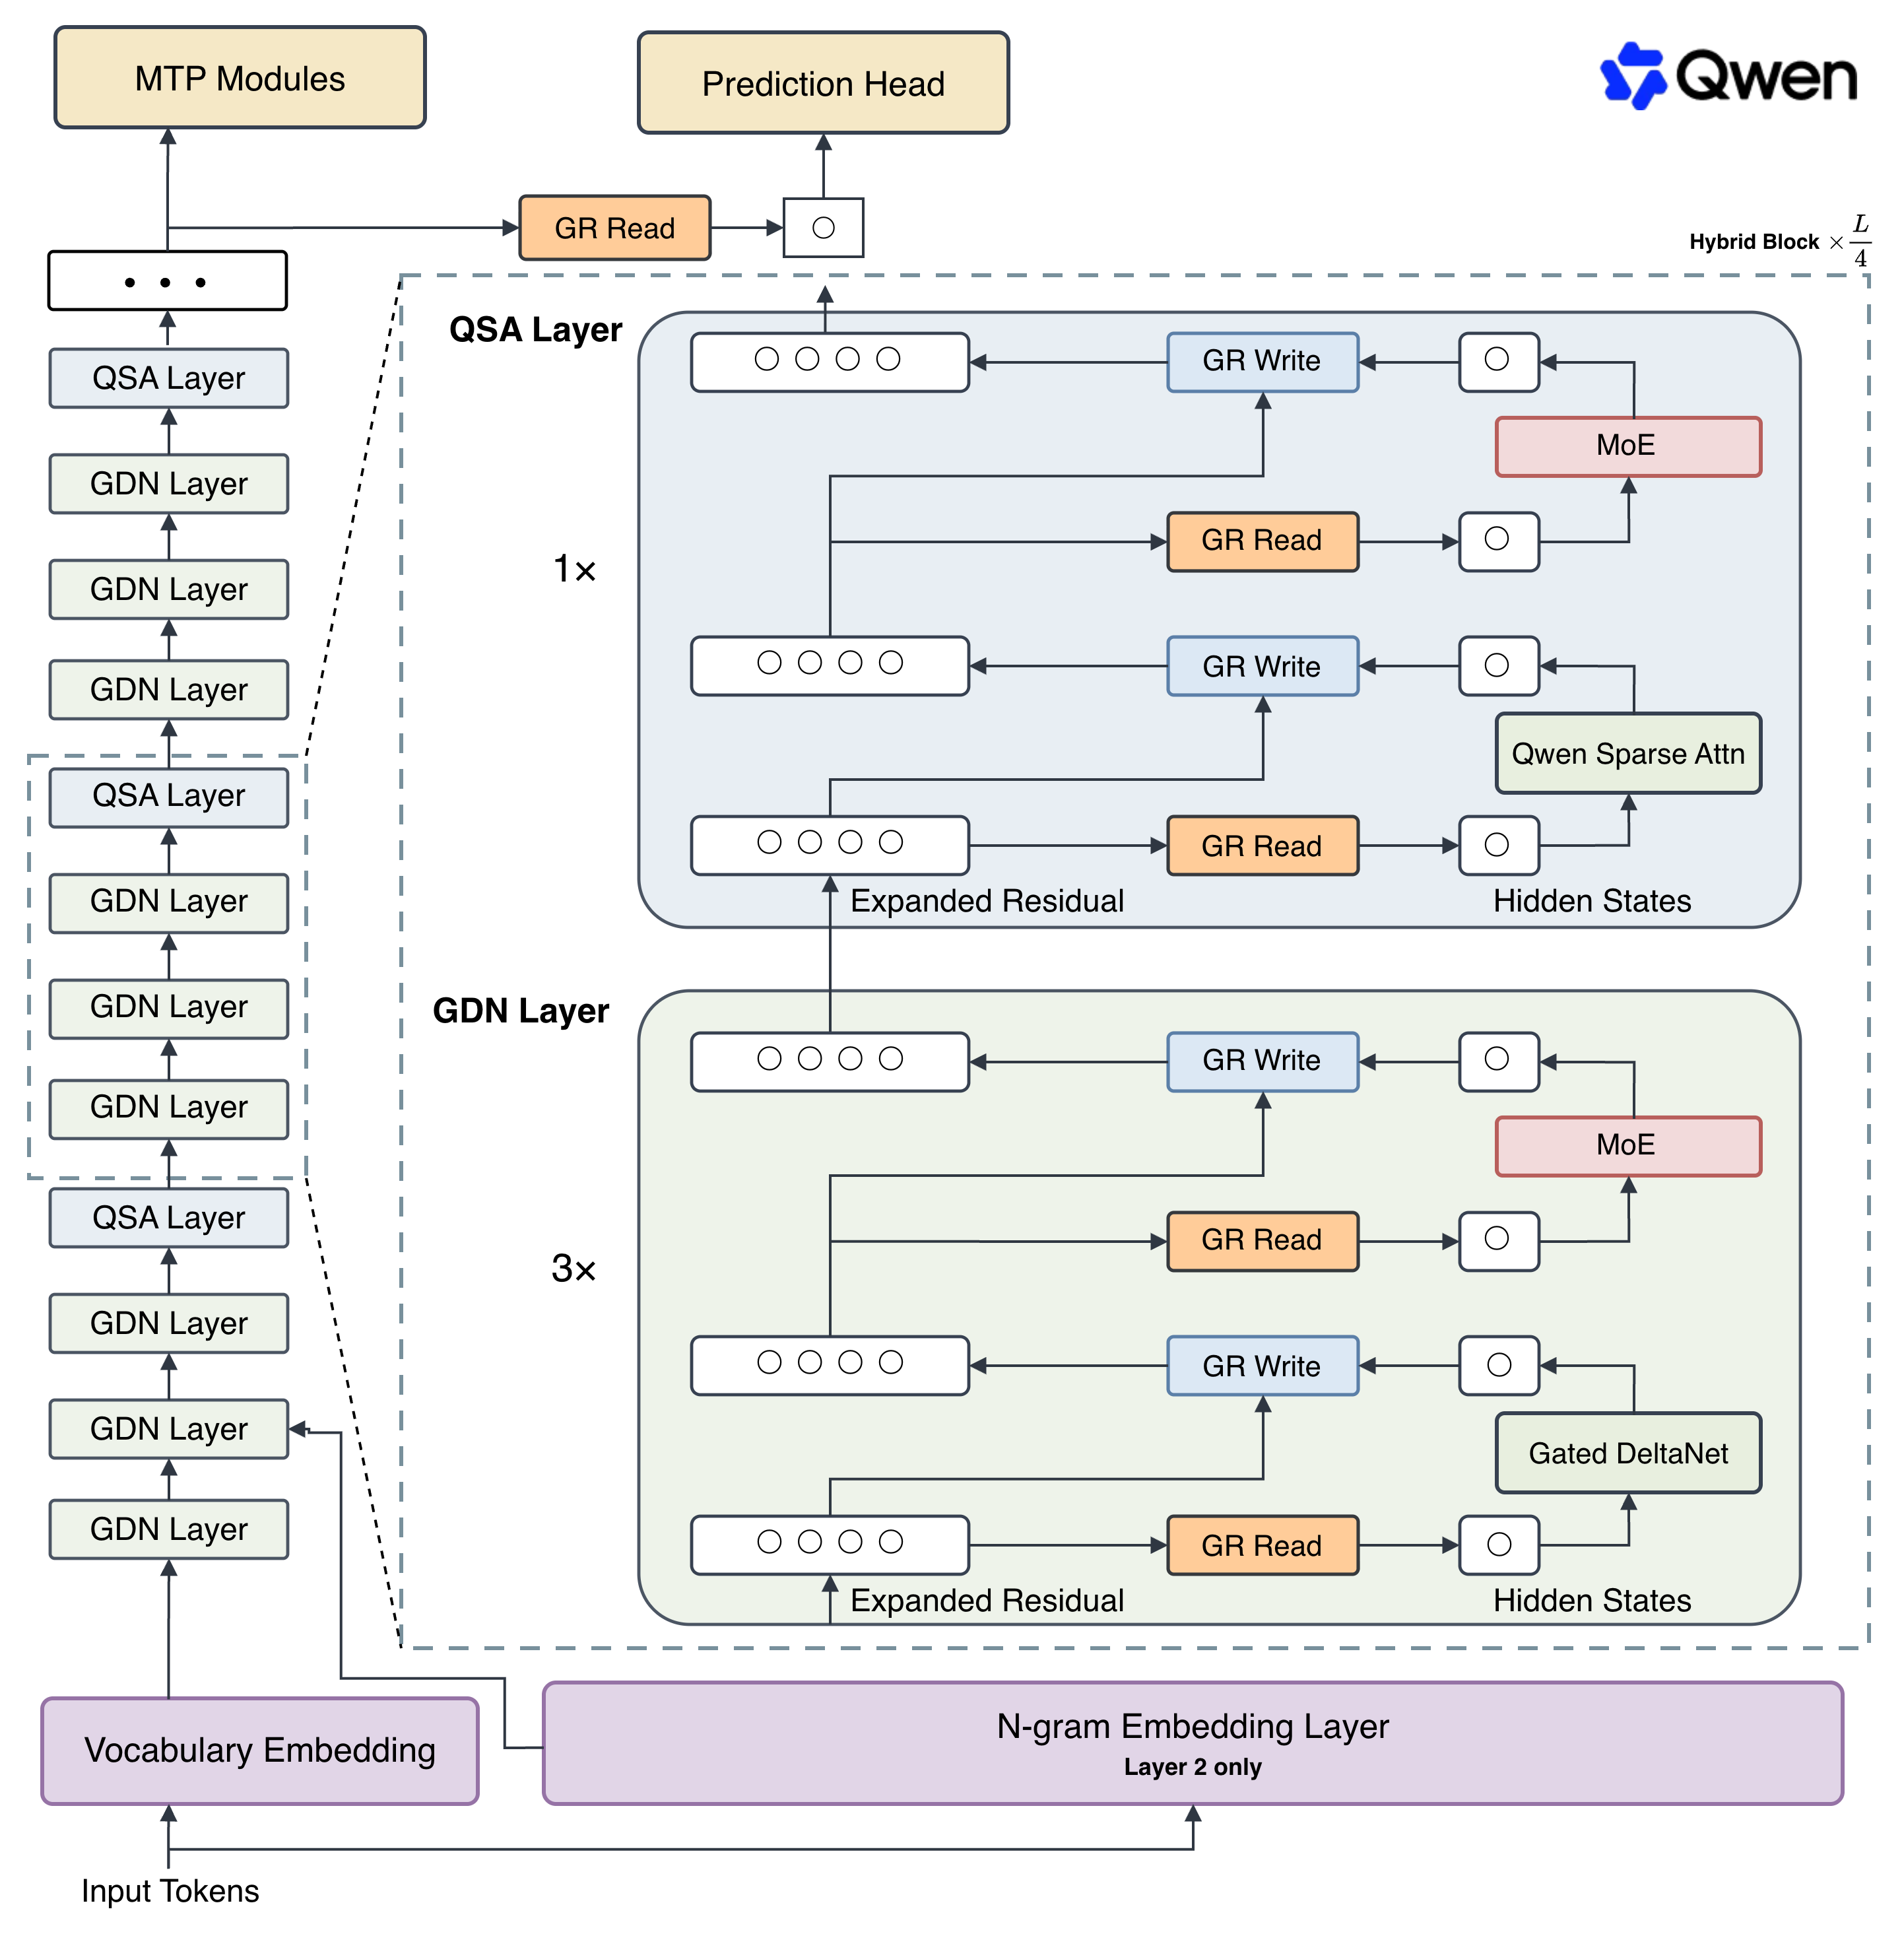
这一架构的实验性预览将支撑 Qwen4,其核心在于对现代大语言模型(LLM)的核心组件在规模化情况下如何交互进行根本性重新思考。
亮点
该架构下的首个开放权重版本是 Qwen3.8-Flash-Next,它引入了:
- 结合 QSA 的混合注意力:Gated DeltaNet 与 Gated Attention 的配对已被重构为 Gated DeltaNet 与 Qwen Sparse Attention(QSA)。QSA 并非选择单个 token 进行处理,而是在微块级别运行。这显著降低了长上下文延迟,随着智能体工作负载日益主导实际使用,这是一项关键收益。
- 门控残差:带归一化的残差流是使深度 LLM 训练可控的关键。门控残差通过逐元素、数据相关的读取门和每分支标量写入门,调节流经加宽残差流的信息。这在各层之间带来更细粒度的表达能力,同时保持训练稳定性并保持较低的推理开销。
- N-gram 嵌入:嵌入为参数扩展提供了一个独特维度,其所需计算更少,且比混合专家(MoE)更易于卸载。通过使用短 n-gram 进行索引,该方法在内存受限的加速器上实现了高效的参数扩展,同时不牺牲质量。
- 定制训练配方:Muon 和 AdamW 优化器被应用于特定的权重类别,以最大化效率。在重新拟合的缩放定律指导下,我们取消了传统的批量大小预热,直接从目标批量大小开始,大幅减少总优化器步数,同时安全支持更大的学习率以实现稳健收敛。
更多详情,请参阅我们的博客文章 Qwen3.8-Flash-Next 和 技术报告。
我们很高兴与您一起开启这一新篇章,并在我们构建下一步时欢迎您的反馈。
模型概览
- 类型:带视觉编码器的因果语言模型
- 训练阶段:预训练与后训练
- Language Model
- 参数量:125B,激活 6B,外加 51B n-gram 嵌入和 4B MTP
- 隐藏维度:2560
- Token 嵌入:248320(填充)
- N-gram 嵌入:20,000,000(第 2 层的 bigram/trigram)
- 层数:48
- Hidden Layout: 12 × (3 × (Gated DeltaNet → MoE) → 1 × (Qwen Sparse Attention → MoE))
- Gated DeltaNet:
- Number of Linear Attention Heads: 48 for V and 16 for QK
- Head Dimension: 128
- Qwen Sparse Attention:
- Number of Attention Heads: 24 for Q and 2 for KV
- Head Dimension: 256
- Rotary Position Embedding Dimension: 64
- Indexer Structure: MQA with 4 Query Heads and 1 Shared Key Head
- Indexer Head Dimension: 128
- Budget: 512 blocks or 2048 tokens
- Mixture Of Experts
- Number of Experts: 512
- Number of Activated Experts: 10 Routed + 1 Shared
- Expert Intermediate Dimension: 640
- Gated Residual:
- Number of Branches: 4
- Bottleneck Rank: 320
- LM Output: 248320 (Padded)
- MTP: 1 layer, trained with multi-steps
- Context Length: 262,144 natively and extensible up to 1,000,000 tokens.
Benchmark Results
Language
| Qwen3.8-Flash-Next | Qwen3.8-27B | Qwen3.7-Plus | DeepSeek-V4-Flash-0731 | Claude-Opus-4.6 (Max) | |
|---|---|---|---|---|---|
# Params |
125B | 27B | 397B | 284B | -- |
# Activated params |
6B | 27B | 17B | 13B | -- |
# N-gram embedding params |
51B | -- | -- | -- | -- |
| Coding | |||||
Agentic coding DeepSWE 1.1 |
58.7 | 42.2 | 16.5 | 54.4 | -- |
Agentic coding SWE-bench Pro |
62.5 | 61.7 | 55.8 | 56.0 | 53.4 |
Multilingual software engineering SWE-bench Multilingual |
81.0 | 73.8 | 75.8 | -- | 77.5 |
Repo-level code generation NL2Repo-Bench |
48.1 | 42.3 | 41.1 | 54.2 | 47.6 |
| Agent | |||||
Long-horizon office work CoWorkBench |
73.9 | 70.7 | 65.1 | 45.1 | 68.2 |
Professional job tasks JobBench |
55.7 | 33.4 | 27.6 | 41.3 | 36.6 |
Frontier agentic tasks Agents' Last Exam |
Pass@1 24.3 Score 51.2 |
Pass@1 20.4 Score 42.9 |
Pass@1 13.2 Score 33.6 |
Pass@1 25.2 Score -- |
-- |
Real-world tool use Toolathlon Verified (Pass@1) |
73.5 | 67.1 | 50.6 | 70.3 | -- |
| General | |||||
Instruction following IFBench |
81.3 | 79.5 | 79.1 | 79.2 | 62.5 |
Scientific reasoning GPQA Diamond |
91.7 | 89.2 | 90.3 | 90.8 | 91.3 |
Multidisciplinary reasoning HLE |
35.9 | 30.8 | 34.7 | 33.8 | 40.0 |
Competitive coding LiveCodeBench v6 |
91.9 | 90.3 | 89.6 | 90.6 | 88.8 |
1. DeepSWE 1.1: evaluated with the Claude Code and mini-SWE-agent harnesses, temp=1.0, top_p=0.95, 256K context window. We report the highest score across the two harnesses; notably, Qwen3.8-Flash-Next performs best on mini-SWE-agent.
2. SWE-bench Pro: except for Claude-Opus-4.6 (Max), for which we report the officially published score, all models are evaluated with the Claude Code harness, temp=1.0, top_p=0.95, 256K context window. Problematic tasks were corrected and all baseline models were re-evaluated on the refined benchmark.
3. SWE-bench Multilingual: evaluated with the mini-SWE-agent harness, temp=1.0, top_p=0.95, 256K context window.
4. NL2Repo-Bench: evaluated with the Claude Code harness. To prevent reward hacking, we disable Bash commands that attempt to access the specific repository, such as pip download, pip install and git clone.
5. CoWorkBench: an in-house cowork benchmark for evaluating long-horizon office and productivity agent tasks across computer science, finance, law, medical and other productivity domains.
6. HLE: judged by GPT-4o.
7. The best result in each row is shown in bold.
8. Empty cells (--): scores are not yet available or are not applicable.
Vision Language
| Qwen3.8-Flash-Next | Qwen3.8-27B | Qwen3.7-Plus | Claude-Opus-4.6 (Max) | |
|---|---|---|---|---|
| Agentic Multimodal Intelligence | ||||
Multimodal tool use ClawEval-MM |
Pass@3 64.4 Average 60.4 |
Pass@3 57.4 Average 56.9 |
Pass@3 57.4 Average 60.1 |
Pass@3 52.5 Average 54.7 |
Application recreation RecreationBench |
49.9 | 47.1 | 30.2 | -- |
Mobile use AndroidWorld |
84.5 | 81.9 | 81.0 | 62.0 |
Computer use OSWorld 2.0 |
Binary 19.4 Partial 52.3 |
Binary 19.4 Partial 48.0 |
Binary 2.8 Partial 21.5 |
-- |
Visual web development Vision2Web |
64.0 | 62.9 | 42.1 | -- |
| General Multimodal Intelligence | ||||
Embodied intelligence ERQA |
72.3 | 65.5 | 69.8 | 40.8 |
Long video understanding LVBench |
76.6 | 72.4 | 76.2 | 63.0 |
Real-world perception RealWorldQA |
88.5 | 85.9 | 86.9 | 73.9 |
Visual math problem solving MathVision |
Without CI 90.6 With CI 95.7 |
Without CI 90.0 With CI 94.6 |
Without CI 90.3 With CI 88.7 |
Without CI 65.5 |
Scientific chart analysis CharXiv (RQ) |
Without CI 84.6 With CI 90.6 |
Without CI 83.7 With CI 90.2 |
Without CI 85.8 With CI 85.9 |
Without CI 66.0 |
1. ClawEval-MM:分数以“pass@3 / 平均分”形式报告。Pass@3 衡量在三次试验中至少一次通过的百分比,平均分是三次试验的平均得分。
2. RecreationBench:内部长时程应用复刻基准,用于评估跨五个平台的混合智能体能力——桌面端(Ubuntu、macOS、Windows)、移动端(Android)和网页端。
3. OSWorld 2.0:分数以“二值 / 部分”形式报告。二值分数是获得完整任务奖励的任务百分比,部分分数汇总所有任务获得的部分奖励。
4. Vision2Web:分数报告为前端、网页和网站三个类别的平均值,使用 Claude Code harness 并由 gpt-5.4-2026-03-05 评判。
5. MathVision、CharXiv(RQ):分数以“无 CI / 有 CI”形式报告。MathVision 中少量错误的标准答案标注经人工核验后已更正。我们的模型分数使用固定提示词评估,例如“Please reason step by step, and put your final answer within \boxed{}.”。对于其他模型,我们报告使用和不使用 \boxed{} 格式的多次运行中的较高分数。
6. 每行最佳结果以粗体显示。
7. 空单元格(--)表示分数尚不可用或不适用。
快速开始
为简化集成,我们建议通过 API 使用 Qwen3.8-Flash-Next。
部署 Qwen3.8-Flash-Next
推理效率和吞吐量在不同框架之间差异显著。 我们建议使用最新的框架版本,以确保最佳性能和兼容性。 对于生产工作负载或高吞吐场景,强烈建议使用专用服务引擎,如 SGLang、KTransformers 或 vLLM。
Qwen3.8-Flash-Next 可使用主流推理框架部署,例如:
- SGLang:Qwen3.8-Flash-Next Cookbook
- vLLM:Qwen3.8-Flash-Next Recipe
- TokenSpeed:Qwen3.8-Flash-Next Recipe
API 使用
Qwen3.8-Flash-Next 模型默认以思考模式运行,在生成最终回复之前会生成由
<think>\n...</think>\n\n表示的思考内容。 如需禁用思考内容并获取直接回复,请参考此处的示例。
我们建议使用以下采样参数集进行生成:
- 思考模式:
temperature=1.0、top_p=0.95、top_k=20、min_p=0.0、presence_penalty=0.0、repetition_penalty=1.0- 指令(或非思考)模式:
temperature=0.7、top_p=0.80、top_k=20、min_p=0.0、presence_penalty=1.5、repetition_penalty=1.0请注意,对采样参数的支持因推理框架而异。
在多轮智能体任务中,降低推理强度并不总能减少整体任务完成时间。虽然它可能产生更快的每轮响应,但也可能导致分析不足、更多失败和重复重试,从而可能增加总延迟和 token 消耗。
Qwen3.8-Flash-Next 支持通过 enable_thinking、preserve_thinking 和 reasoning_effort 控制思考行为。
Chat Completions API
Chat Completions API 可与大多数推理框架以及 Qwen Cloud 配合使用。 开始之前,请确保已安装并配置好 API key 和 API base URL,例如:
pip install -U openai

# Set the following accordingly
export OPENAI_BASE_URL="http://localhost:8000/v1"
export OPENAI_API_KEY="EMPTY"
纯文本输入
from openai import OpenAI
# Configured by environment variables
client = OpenAI()

messages = [
    {"role": "user", "content": "Write a Python function to merge two sorted linked lists."},
]

completion = client.chat.completions.create(
    model="Qwen/Qwen3.8-Flash-Next",
    messages=messages,
    extra_body={
        "chat_template_kwargs": {
            "enable_thinking": True,  # on by default
            "preserve_thinking": True, # on by default
        },
    },
    reasoning_effort="xhigh",  # xhigh by default; supported levels are xhigh, medium, and low
    stream=True,
    stream_options={"include_usage": True},
)

reasoning_content = ""
answer_content = ""
is_answering = False
print("\n" + "=" * 20 + "Reasoning" + "=" * 20 + "\n")

for chunk in completion:
    if not chunk.choices:
        print("\nUsage:")
        print(chunk.usage)
        continue

    delta = chunk.choices[0].delta

    if hasattr(delta, "reasoning_content") and delta.reasoning_content is not None:
        if not is_answering:
            print(delta.reasoning_content, end="", flush=True)
        reasoning_content += delta.reasoning_content
    elif hasattr(delta, "reasoning") and delta.reasoning is not None:
        if not is_answering:
            print(delta.reasoning, end="", flush=True)
        reasoning_content += delta.reasoning

    if hasattr(delta, "content") and delta.content:
        if not is_answering:
            print("\n" + "=" * 20 + "Answer" + "=" * 20 + "\n")
            is_answering = True
        print(delta.content, end="", flush=True)
        answer_content += delta.content

messages.append({
    "role": "assistant",
    "content": answer_content,
    "reasoning_content": reasoning_content,
    "reasoning": reasoning_content,
})
图像输入
from openai import OpenAI
# Configured by environment variables
client = OpenAI()

messages = [
    {
        "role": "user",
        "content": [
            {
                "type": "image_url",
                "image_url": {
                    "url": "https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen3.5/demo/CI_Demo/mathv-1327.jpg"
                }
            },
            {
                "type": "text",
                "text": "The centres of the four illustrated circles are in the corners of the square. The two big circles touch each other and also the two little circles. With which factor do you have to multiply the radii of the little circles to obtain the radius of the big circles?\nChoices:\n(A) $\\frac{2}{9}$\n(B) $\\sqrt{5}$\n(C) $0.8 \\cdot \\pi$\n(D) 2.5\n(E) $1+\\sqrt{2}$"
            }
        ]
    }
]

chat_response = client.chat.completions.create(
    model="Qwen/Qwen3.8-Flash-Next",
    messages=messages,
)
print("Chat response:", chat_response)
视频输入
from openai import OpenAI
# Configured by environment variables
client = OpenAI()

messages = [
    {
        "role": "user",
        "content": [
            {
                "type": "video_url",
                "video_url": {
                    "url": "https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen3.5/demo/video/N1cdUjctpG8.mp4"
                }
            },
            {
                "type": "text",
                "text": "How many porcelain jars were discovered in the niches located in the primary chamber of the tomb?"
            }
        ]
    }
]

chat_response = client.chat.completions.create(
    model="Qwen/Qwen3.8-Flash-Next",
    messages=messages,
)

# When vLLM is launched with `--media-io-kwargs '{"video": {"num_frames": -1}}'`,
# video frame sampling can be configured via `extra_body` (e.g., by setting `fps`).
# This feature is currently supported only in vLLM.
#
# By default, `fps=2` and `do_sample_frames=True`.
# With `do_sample_frames=True`, you can customize the `fps` value to set your desired video sampling rate.
# chat_response = client.chat.completions.create(
#     model="Qwen/Qwen3.8-Flash-Next",
#     messages=messages,
#     extra_body={
#         "mm_processor_kwargs": {"fps": 2, "do_sample_frames": True},
#     },
# )

print("Chat response:", chat_response)
指令(或非思考)模式
Qwen3.8-Flash-Next 在回复前会默认进行思考。 你可以通过配置 API 参数来获得模型不进行思考的直接回复。 例如,
from openai import OpenAI
# Configured by environment variables
client = OpenAI()

messages = [
    {
        "role": "user",
        "content": [
            {
                "type": "image_url",
                "image_url": {
                    "url": "https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen3.5/demo/RealWorld/RealWorld-04.png"
                }
            },
            {
                "type": "text",
                "text": "Where is this?"
            }
        ]
    }
]

chat_response = client.chat.completions.create(
    model="Qwen/Qwen3.8-Flash-Next",
    messages=messages,
    temperature=0.7,
    top_p=0.8,
    presence_penalty=1.5,
    extra_body={
        "top_k": 20,
        "chat_template_kwargs": {"enable_thinking": False},
    },
)
print("Chat response:", chat_response)
如果你使用的是 Qwen Cloud 的 API,除了修改
model之外,请使用"enable_thinking": False而不是"chat_template_kwargs": {"enable_thinking": False}。
禁用保留思考
默认情况下,Qwen3.8-Flash-Next 会保留所有历史消息中的思考块,从而在整个对话中维持完整的推理轨迹。这种行为称为保留思考,可确保上下文的完整连续性,尤其适用于对决策一致性和减少冗余推理有较高要求的智能体场景。它还能提升 KV 缓存利用率,在思考模式和非思考模式下均能优化推理效率。
如果你希望仅保留最新一条用户消息中的思考块,可以通过将 preserve_thinking 设置为 False 来禁用此行为:
from openai import OpenAI

# Configured by environment variables
client = OpenAI()
messages = [...]
chat_response = client.chat.completions.create(
    model="Qwen/Qwen3.8-Flash-Next",
    messages=messages,
    extra_body={
        "chat_template_kwargs": {"preserve_thinking": False},
    },
)
print("Chat response:", chat_response)
如果你使用的是 Qwen Cloud 的 API,除了修改
model之外,请直接使用"preserve_thinking": False,而不要将其包裹在chat_template_kwargs中。
最佳实践
为达到最佳性能,我们推荐以下设置:
采样参数:我们建议使用以下采样参数组合:
- 思考模式:
temperature=1.0、top_p=0.95、top_k=20、min_p=0.0、presence_penalty=0.0、repetition_penalty=1.0 - 指令(或非思考)模式:
temperature=0.7、top_p=0.80、top_k=20、min_p=0.0、presence_penalty=1.5、repetition_penalty=1.0
对于支持的框架,你可以在 0 到 2 之间调整
presence_penalty参数以减少无休止的重复。不过,使用较高的值偶尔会导致语言混杂以及模型性能略有下降。- 思考模式:
充足的输出长度:为优化智能体任务上的性能,我们建议分配足够的输出长度,以便模型生成详细且全面的回复。对于支持为内部推理和最终输出分别设置 token 上限的框架,我们建议在 1M 上下文长度内采用以下配置:
- 推理内容:将最大输出长度设置为 262,144 个 token。
- 最终回复:将最大输出长度设置为 131,072 个 token。
这些设置既为复杂推理提供了必要容量,又确保为高质量的最终交付成果留出充足空间。
处理超长文本:Qwen3.8-Flash-Next 原生支持最长 262,144 个 token 的上下文长度。对于总长度(包括输入和输出)超过此限制的长程任务,我们建议使用 RoPE 缩放技术来有效处理长文本,例如 YaRN。
目前已有多个推理框架支持 YaRN,例如 vLLM、SGLang 和 TokenSpeed。 一般来说,在支持的框架中启用 YaRN 有两种方式:
修改模型配置文件:
在
config.json文件中,将text_config中的rope_parameters字段改为:{ "mrope_interleaved": true, "mrope_section": [ 11, 11, 10 ], "rope_type": "yarn", "rope_theta": 10000000, "partial_rotary_factor": 0.25, "factor": 4.0, "original_max_position_embeddings": 262144 }传递命令行参数:
对于 vLLM,你可以使用
VLLM_ALLOW_LONG_MAX_MODEL_LEN=1 vllm serve ... --hf-overrides '{"text_config": {"rope_parameters": {"mrope_interleaved": true, "mrope_section": [11, 11, 10], "rope_type": "yarn", "rope_theta": 10000000, "partial_rotary_factor": 0.25, "factor": 4.0, "original_max_position_embeddings": 262144}}}' --max-model-len 1000000对于 SGLang,你可以使用
SGLANG_ALLOW_OVERWRITE_LONGER_CONTEXT_LEN=1 python -m sglang.launch_server ... --json-model-override-args '{"text_config": {"rope_parameters": {"mrope_interleaved": true, "mrope_section": [11, 11, 10], "rope_type": "yarn", "rope_theta": 10000000, "partial_rotary_factor": 0.25, "factor": 4.0, "original_max_position_embeddings": 262144}}}' --context-length 1000000对于 TokenSpeed,你可以使用
TOKENSPEED_ALLOW_OVERWRITE_LONGER_CONTEXT_LEN=1 tokenspeed serve ... --hf-overrides '{"text_config": {"rope_parameters": {"mrope_interleaved": true, "mrope_section": [11, 11, 10], "rope_type": "yarn", "rope_theta": 10000000, "partial_rotary_factor": 0.25, "factor": 4.0, "original_max_position_embeddings": 262144}}}' --max-model-len 1000000
所有知名的开源框架实现的都是静态 YaRN,这意味着缩放因子不随输入长度变化而保持恒定,这可能会影响较短文本上的性能。 我们建议仅在需要处理长上下文时才修改
rope_parameters配置。 同时建议根据需要修改factor。例如,如果你的应用典型上下文长度为 524,288 个 token,最好将factor设置为 2.0。长视频理解:为优化纯文本和图像的推理效率,已发布的
video_preprocessor_config.json中的size参数被保守配置。建议将 video_preprocessor_config 文件中的longest_edge参数设置为 469,762,048(对应 224k 视频 token),以便对小时级视频启用更高帧率采样,从而获得更优性能。例如,{"longest_edge": 469762048, "shortest_edge": 4096}
引用
如果您觉得我们的工作有帮助,欢迎引用。
@techreport{qwen2026design,
    title       = {On the Design of {Qwen3.8-Next} Architecture: Evaluation, Efficiency, and Training Stability},
    author      = {{Qwen Team}},
    institution = {Alibaba Group},
    month       = {August},
    year        = {2026}
}

@misc{qwen3.8flashnext,
    title  = {{Qwen3.8-Flash-Next}: A New Architecture, Towards Ultimate Cost-Efficiency},
    author = {{Qwen Team}},
    month  = {August},
    year   = {2026},
    url    = {https://qwen.ai/blog?id=qwen3.8-flash-next}
}
- 上月下载量
- 3,743,202
Safetensors
Qwen/Qwen3.8-Flash-Next 的模型树
使用 Qwen/Qwen3.8-Flash-Next 的 Spaces 31
包含 Qwen/Qwen3.8-Flash-Next 的合集
来源:Qwen 模型发布 · hf-mirror.com