MoEngage 如何用 AgentCore Gateway 把 400 多个 API 变成智能体工具
How MoEngage turned over 400 APIs into agent tools with AgentCore Gateway
MoEngage 与 AWS 团队撰文介绍,MoEngage 使用 Amazon Bedrock AgentCore Gateway 将约 400 个 VPC 私有 REST API 转为按权限限定的智能体工具,估算节省约六个月的平台工程投入。
This post was co-written with Nikhil Kumar and Shakir Khan from MoEngage.
When engineering teams start building AI agents, the capabilities those agents need usually already exist as internal APIs. Campaign creation, segment queries, delivery stats. The challenge isn’t building new functionality. The challenge is making hundreds of private APIs safely reachable by agents without exposing them to the public internet, without giving models control over identity, and without flooding context windows with hundreds of tool definitions.
MoEngage, the agentic customer engagement platform that more than 1,350 consumer brands use to deliver personalized experiences across push, email, in-app, SMS, WhatsApp, and RCS, faced exactly this problem. Behind the product sit roughly 400 internal REST APIs, built by 25 engineering teams, running in private virtual private clouds (VPCs) across seven AWS Regions. MoEngage isolates these APIs regionally to meet data residency commitments and doesn’t expose them to the public internet. The capability the agents needed was already running in production. Making it reachable, safely, was the hard part.
In this post, we walk through how MoEngage used AgentCore Gateway, a capability of Amazon Bedrock AgentCore, to turn those private APIs into permission-scoped agent tools. The approach saved MoEngage an estimated six months of platform engineering effort, and onboarding a new API now takes hours instead of days. No product team wrote Model Context Protocol (MCP) server code, no networking was provisioned per integration, and no public endpoint exists anywhere in the path.
Why 20 MCP servers was the wrong answer
The Model Context Protocol (MCP) gives agents a standard way to discover and call tools. The straightforward path to adopting it is for each team to expose its own MCP server. MoEngage costed that out and rejected it.
Over 20 MCP servers means over 20 deployments to monitor, patch, and keep protocol-compatible as MCP evolves. Cross-domain agents, the useful ones that read a campaign, check its segment, and inspect delivery stats, would need to connect to several servers and reconcile them. And every team would need MCP expertise unrelated to its actual product work.
So MoEngage established the principle that shaped everything that followed: Individual engineering teams do not implement MCP. Teams build REST APIs and declare which operations should be tools. The AI Platform team owns the MCP layer end to end. A team’s responsibility ends at a well-described OpenAPI spec.
That principle immediately created three requirements: a central tool surface that agents connect to once rather than per-service, per-agent authorization enforced server-side rather than by convention, and private connectivity that does not need to be rebuilt for every new API.
Building all of this from scratch was an option. A custom central MCP server would solve the 20-servers problem but leave MoEngage building a tool-generation pipeline, a policy file format, a tool-alias registry for renames, and circuit breakers. All custom code, all owned by one team, all of it undifferentiated work that does not make MoEngage’s agents smarter or its customers’ campaigns better.
Four constraints that shaped the architecture
Before evaluating any solution, MoEngage defined four constraints. All four had to be met simultaneously. A solution that addressed two but broke the third and fourth was not viable.
Nothing gets a public endpoint. MoEngage’s internal APIs are VPC-private by policy. Any solution that required exposing them, even behind additional authentication, was a non-starter. The conventional workaround is per-integration networking: a NAT gateway here, a reverse proxy there, a VPN tunnel for the third one. Multiply that by seven Regions and the operational surface grows faster than the set of agents does. Every new API would mean another networking change request, another set of security reviews, another piece of infrastructure to maintain.
Identity can’t be an agent’s decision. Every internal API call carries tenant, user, role, and database context. If that context is a large language model (LLM)-visible tool parameter, a model can get it wrong or be talked into changing it. MoEngage needed identity to be structurally out of the model’s reach, injected by the calling service and not surfaced as something the model can set or override.
A 400-tool catalog doesn’t fit in a context window. At roughly 50 tokens of JSON schema per tool, a full tools/list across the estate is over 20,000 tokens transmitted on every connection. That token budget is spent before the agent does anything useful, and it crowds out the context the agent actually needs to reason about the task. Client-side filtering (tool_filter in ADK or the MCP SDK) doesn’t fix this. The full catalog has already crossed the wire, and filtering by client convention isn’t an authorization boundary. An agent that is not supposed to see write operations shouldn’t receive them in the first place.
That last constraint is the one that avoided the obvious alternatives. A custom central MCP server solves the 20-servers problem but still leaves MoEngage building a tool-generation pipeline, a policy file format, a tool-alias registry for renames, and circuit breakers. All custom code, all owned by one team, none of it making MoEngage’s product better.
How AgentCore Gateway maps to those constraints
Amazon Bedrock AgentCore Gateway is a fully managed MCP server. You register OpenAPI specs as targets and the gateway generates MCP tools from them, then routes calls to the backing services. Four properties mapped directly onto MoEngage’s constraints.
OpenAPI in, MCP tools out. There’s no MCP server to build or operate, and no separate artifact to keep in sync with the API. The spec teams already maintain is the tool definition. Each operation becomes a tool named Target___operationId, for example CampaignsAPI___searchCampaigns. When the spec changes, the tool changes. When a team adds an endpoint, the tool appears. When a team removes one, the tool disappears. No deployment, no protocol expertise, no coordination with the AI Platform team.
Cedar policies, evaluated before the catalog is serialized. The AgentCore policy engine uses partial evaluation to filter tools/list per principal. Each agent authenticates as its own IAM role, and its Cedar policy determines which tools it can see and call. This is what makes 400 tools tractable. It isn’t client-side filtering after the fact, but server-side scoping before the response is built.
A campaign QA bot, for example, gets read access to campaign and segment tools but can’t call a write operation:
permit(
    principal == Agent::"campaign-qa-bot-v1",
    action == Action::"tools/call",
    resource in ToolGroup::"campaigns-read"
);

forbid(
    principal == Agent::"campaign-qa-bot-v1",
    action == Action::"tools/call",
    resource in ToolGroup::"write-actions"
);
The bot doesn’t see write tools in its tools/list response. There’s nothing to filter on the client side because the tools weren’t sent.
Managed egress over Amazon VPC Lattice. The gateway reaches MoEngage’s internal services through AgentCore managed egress rather than through networking MoEngage builds and operates. Inbound, the gateway is reachable only through a VPC interface endpoint with private DNS. There’s no public path to it. Onboarding a new API adds a target, not a network topology change. This is the property that broke the multiply by seven Regions problem. The networking exists once and every API uses it.
Semantic search as a gateway capability. With the x_amz_bedrock_agentcore_search capability, an agent can find tools by describing the task instead of naming the tool. It removed the need for a custom discovery layer. It also removed rename fragility as a side effect: if get_segment_user_count becomes get_segment_size, an agent searching for segment user count still finds it, because matching happens on description rather than identifier.
The architecture in practice
The request flow from agent to internal API is short, and every layer has a specific job. Agent services connect through a VPC interface endpoint to AgentCore Gateway, which evaluates Cedar policies and routes tool calls through managed egress over Amazon VPC Lattice to internal APIs.
The following diagram shows how the components connect.
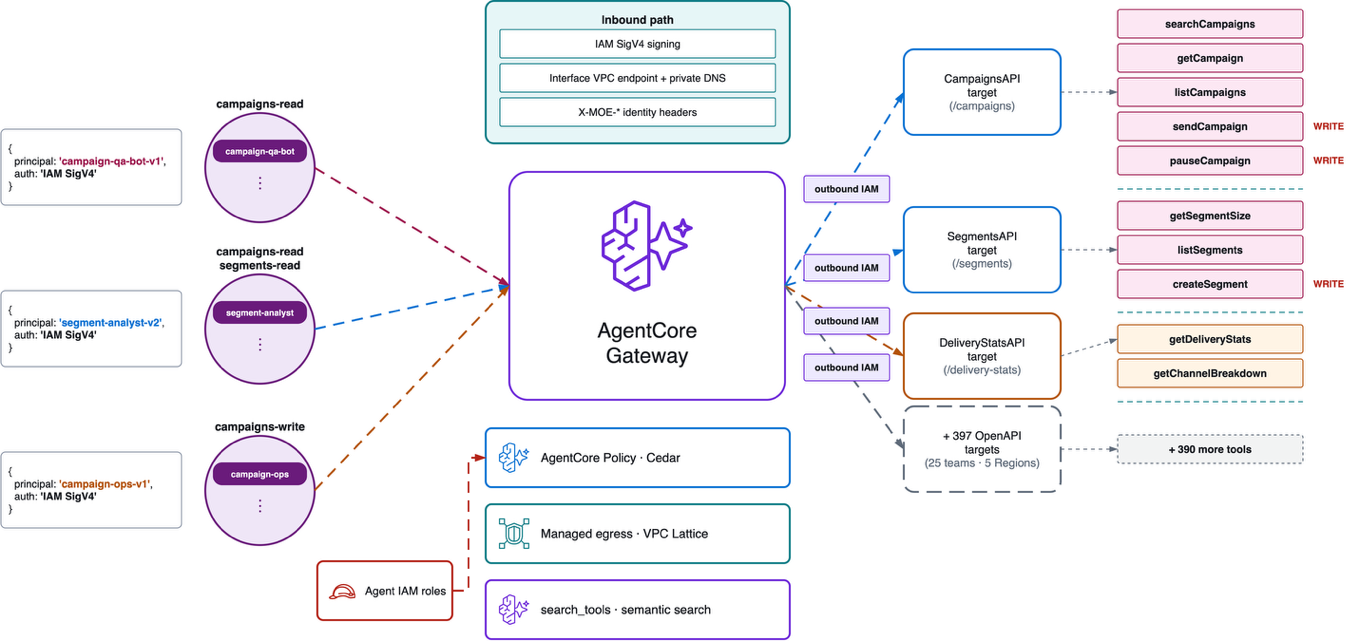
Figure 1: MoEngage AgentCore Gateway architecture
An agent service running on Amazon Elastic Compute Cloud (Amazon EC2) or in a container calls the MCP client. The client can be the official MCP SDK, LangChain, Google ADK, or MoEngage’s own agent runner. The client signs the request with SigV4 using the AWS Identity and Access Management (IAM) role the service already has. The request travels over HTTPS to a VPC interface endpoint with private DNS. There’s no public hop. AgentCore Gateway receives the request and evaluates Cedar policies to determine what this principal can see or call. It then routes tool invocations through managed egress over Amazon VPC Lattice to the internal API.
MoEngage made two authentication decisions worth calling out.
First, they chose SigV4 over JWT for the internal gateway. Agents here are services that already have IAM roles. With SigV4, they can sign with credentials they already have. Nothing new to issue, rotate, or store. MoEngage’s separate public MCP server, which serves human-authenticated sessions from Claude and other clients, uses OIDC JWTs on AgentCore runtime. That is a different surface with different requirements.
Second, identity travels as headers, not as tool arguments. Tenant, user, role, and database context are converted by the client library from a small Identity object into X-MOE-* headers. The model doesn’t see them and can’t set them. One detail matters for anyone building something similar: Because SigV4 signing occupies the Authorization header, caller-forwarded bearer tokens must move elsewhere. MoEngage propagates it as a dedicated MoEngage-prefixed header. Header propagation is also capped, so the set of headers is deliberate rather than accumulated.
Discovery and execution have different identity requirements. Listing and searching tools carries no tenant identity. Only tools/call does. That separation keeps discovery cheap and makes the audit trail unambiguous. Every identity-bearing request is an actual data access.
Even with Cedar scoping an agent to a subset of the catalog, the subset can be large. MoEngage’s client library exposes a single meta-tool, search_tools, to the model. The model describes what it needs, the gateway’s semantic search returns candidates, and only those candidates become callable for the rest of the turn. The full catalog doesn’t enter context. The agent’s context contains one tool definition at the start and a handful of relevant ones after a search, instead of several hundred definitions it will never use.
Onboarding a new API
A team exposing an API as an agent tool adds a block to its existing OpenAPI spec:
paths:
  /campaigns:
    get:
      operationId: listCampaigns
      description: |
        Returns a paginated list of campaigns. Supports filtering by
        status, channel, date range, and tags.
      x-moe-mcp:
        expose:
          external: false
          internal: true
        tool_description: |
          Find campaigns by status or channel. Returns campaign ID, name,
          status, and channel. Use the returned campaign_id with
          get_campaign for full details, or send_campaign to launch it.
        param_overrides:
          status:
            description: |
              Filter by campaign status. Use 'active' for running
              campaigns, 'scheduled' for upcoming. Omit for all.
Four design choices in that block are worth explaining.
Exposure is explicit opt-in. An endpoint with no x-moe-mcp block is not a tool. Continuous integration (CI) does not warn about its absence, because for most endpoints absence is the correct state. Cache-warmup routes and migration triggers are not agent tools, and nothing should nudge a team toward making them one. With the internal and external flags, a team can expose an operation to internal agents, to the public MCP server, or to both, independently.
Tool descriptions aren’t API descriptions. An API description tells a developer reading docs what an endpoint returns. A tool description tells a model when to reach for this tool and what to pass. MoEngage found that reusing API descriptions verbatim led to poor tool selection. Models picked tools based on implementation detail (“Returns a paginated list”) rather than intent (“Find campaigns by status or channel”). The tool_description and param_overrides fields exist specifically to give teams a place to write model-facing text without changing their developer-facing docs.
The CI pipeline handles everything from spec to running tool. When a team pushes a spec change, the pipeline validates the x-moe-mcp block, registers the target with AgentCore Gateway, and applies the Cedar policy. No manual steps, no tickets to the AI Platform team. A team that has never thought about MCP can have an operation available as an agent tool in the time it takes the pipeline to run.
The client library comes in two modes. A plug-in mode wraps the AgentCore Gateway MCP server inside LangChain, Google ADK, or an MCP-compatible framework as a tool provider. An agent runner mode runs a complete agent loop for teams that want a standalone agent without adopting a framework.
What MoEngage runs today
MoEngage’s AgentCore Gateway deployment runs in seven AWS Regions today. The gateway serves roughly 400 registered API operations to 10 internal agents. No product team has written MCP server code. No product team has provisioned networking for an agent integration. No product team has implemented Cedar policies. The AI Platform team owns all of that, and the cost of onboarding a new API is a spec annotation and a CI run. AgentCore feature availability varies by Region. For supported Regions, see the Amazon Bedrock AgentCore documentation.
The system has been running in production for three months. The agents span the workflow a marketing team member touches daily. A campaign QA agent validates targeting rules and content before launch. A delivery health agent monitors send rates and bounce patterns across channels. A segment builder agent translates natural-language audience descriptions into segment queries. Each agent authenticates with its own IAM role, sees only the tools its Cedar policy permits, and discovers tools by describing the task rather than memorizing tool names. By removing the need to build and operate 20 separate MCP servers and provision per-API networking across seven Regions, MoEngage estimates the approach saved approximately six months of engineering effort. Onboarding a new API now takes hours of spec annotation instead of days of networking provisioning and security review.
The search-first pattern changed how MoEngage thinks about agent design. New agents start with zero hardcoded tool references. They describe intent, receive candidates, and call what they find. When a team renames an operation or ships a new one, existing agents pick it up without a code change.
Conclusion
The key insight behind MoEngage’s approach is a separation of concerns that maps to how engineering organizations actually work. Product teams own APIs and describe them well. A platform team owns the protocol layer, the policy layer, and the connectivity layer. AgentCore Gateway made that split practical by removing the undifferentiated work in between: no MCP server code, no per-API networking, no client-side filtering pretending to be authorization.
The result is an agent system where adding a new tool is a spec change, restricting access is a policy change, and neither requires the other team to be involved.
To get started with AgentCore Gateway, see the Amazon Bedrock AgentCore documentation. For Cedar policy authoring, see the Cedar policy language reference. For private connectivity patterns, see the Amazon VPC Lattice documentation.
To discuss a similar architecture for your organization, contact your AWS account team or reach out to AWS.
About the authors

Nikhil Kumar
Nikhil is a Lead Software Engineer in the CTO’s office at MoEngage, where he leads the AI Labs team building agentic AI capabilities. His work spans MCP server and tool-catalog architecture, LLM gateway and routing infrastructure, and evaluating agent frameworks for both internal tooling and public agent experiences. He has over 4 years of experience building software and cloud infrastructure at scale.

Shakir Khan
Shakir is an Architect at MoEngage, where he leads API governance and builds core streaming infrastructure powering the company’s customer engagement platform. His work spans gateway architecture, real-time streaming with Flink and Kafka, and large-scale data migrations. He has over 11 years of experience designing systems that serve billions of customer interactions, including 5 years at MoEngage.

Bhupesh Chadha
Bhupesh is a Principal Account Manager at Amazon Web Services, where he partners with independent software vendors (ISVs) to align their platform strategy with their business goals. He works with C-suite and senior leadership to accelerate growth, bring new capabilities to market, and turn technical investments into customer reach and differentiation.

Anant Murarka
Anant is a Solutions Architect at Amazon Web Services, where he works with ISV customers to design multi-tenant architectures and productionize AI-driven solutions. His areas of expertise include agentic AI, agent orchestration patterns, responsible AI, and helping product companies adopt generative AI on AWS. Outside of work, Anant is passionate about exploring how emerging AI paradigms reshape the way software products are built and delivered.
来源:AWS Machine Learning Blog · aws.amazon.com